Rebuild vs Refactor: Should You Rewrite Your Legacy Internal Software?
Your internal system is slow, fragile and hard to change. Should you start over or fix what you have? Here are the signals for each path, the safer middle route, and a checklist to make the call.
Every business that runs the same internal tool for a few years reaches this moment. The system mostly works, but every change takes too long, and someone asks, "Wouldn't it be faster to just rebuild it?"
The short answer: refactor when the software still does the right job and the pain is in how the code is built. Rebuild only when the system is doing the wrong job, sits on technology you can no longer safely run, or costs more to keep alive than to replace. For most legacy internal software, the best answer is neither extreme: replace it piece by piece while the old system keeps running, so you get a new system without betting the business on one launch day.
Here is how to tell which situation you are in.
What is the difference between rebuilding and refactoring?
Refactoring means improving the code you have without changing what it does for users. You clean up messy sections, add tests, upgrade libraries and fix slow queries. The system keeps running the whole time, and users notice that things break less.
Rebuilding (or rewriting) means writing a new system to replace the old one: new codebase, often a new stack, sometimes a new database design. When it is ready, everyone switches over and the old one is retired.
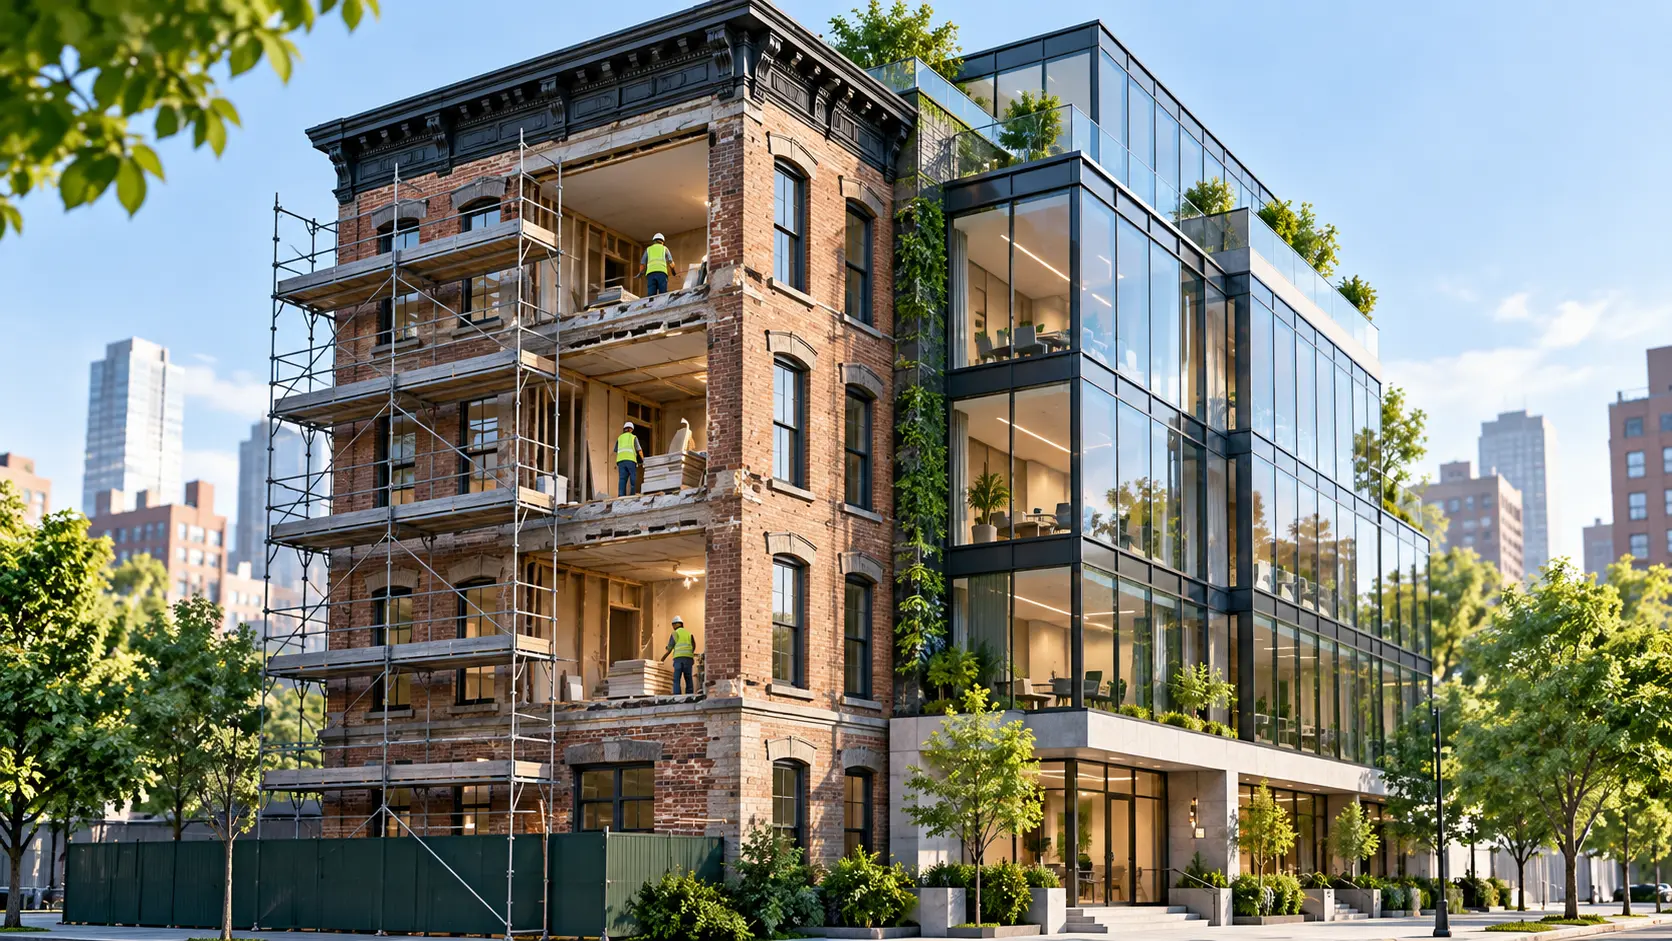
There is a third option that sits between them: incremental replacement, often called the strangler pattern. You still end up with new software, but you get there in small, reversible steps instead of one big switch. For most legacy internal tools, that middle path is where the decision lands, so it gets its own section below.
When does refactoring make sense?
Refactor when the problem is the code, not the purpose. Signals that point toward refactoring:
- The workflow is still right. Your team uses the tool the way it was designed. Complaints are about speed, bugs or how long changes take, not "this does not match how we work."
- The stack is still supported. The language, framework and database still get security updates, and you can hire people who know them.
- The pain is concentrated. Most problems live in a few modules (the billing logic, the reporting screen, one integration). Fixing those removes most of the friction.
- The data model is sound. Your tables and relationships make sense. Bad data models are much harder to fix in place than bad code.
- There is knowledge to save. Years of edge cases, odd customer rules and bug fixes live in that code. Refactoring keeps all of it.
Refactoring is unglamorous, but it is usually the cheapest way to get a system that is easy to change again, and it never leaves you without a working tool.
When is rebuilding the right call?
Sometimes starting over really is the answer. Signals that point toward a rebuild:
- The business has changed shape. You went from one location to twelve, or from one product to subscriptions. The software's core assumptions are wrong, not just its code.
- The platform is dead or dangerous. It runs on an unsupported framework, an old database version without security patches, or a desktop app that only works on one machine in the back office.
- Nobody can safely change it. The original developer is gone, there are no tests, no documentation, and every change causes a surprise somewhere else.
- Integration is impossible. You need the system to talk to your CRM, accounting or customer portal, and the architecture simply cannot expose the data.
- Maintenance costs keep climbing. If you are paying more each year just to keep it running, and that number is approaching what a replacement would cost over a few years, the math starts to favor rebuilding. Our guide to software maintenance cost after launch covers what normal upkeep looks like, so you can tell whether yours is out of line.
A rebuild is also the moment to ask whether you need custom software at all. If a mature product now does the job, compare that route first. We walk through that choice in custom software vs off-the-shelf.
Why are big rewrites so risky?
Because a full rewrite asks you to stop the world. You keep paying for the old system while building the new one, and the new one has to match years of features before anyone can use it.
The common failure patterns:
- Hidden rules get lost. The old code handles edge cases nobody wrote down: a discount for one client, a tax rule for one county, a supplier's odd file format. The new system ships without them and things quietly go wrong.
- The target keeps moving. New requests must go into both the old system (it is live) and the new one (it must match). You pay twice.
- Value arrives late. Nobody benefits until the switch. If the project runs long, months of spend have produced nothing your team can use.
- Cutover day carries all the risk. Data migration, user training and every bug land at once.
Stephan Schwab, writing about governing modernization projects, notes that a big-bang replacement concentrates all the switching risk into one moment, and requires understanding the entire legacy system before replacing any part of it. That is the core problem. You are betting that you understand everything, and with old internal tools you usually do not.
What is the strangler pattern, and why does it work?
The strangler fig pattern (named after a vine that grows around a tree until it replaces it) lets you rebuild without a big-bang switch. You put a layer in front of the old system that decides where each request goes. Then you rebuild one slice at a time, send traffic for that slice to the new code, and retire the old part once nothing depends on it.
Microsoft's architecture guidance describes this as incrementally migrating a legacy system behind a façade, so users keep the same entry point and do not need to know a migration is happening. When the last slice moves, you remove the old system and, eventually, the façade.
For a typical internal tool, it might look like this:
- Put the old app behind a router or API layer you control.
- Pick a painful, self-contained slice, such as reporting or customer intake.
- Rebuild it with tests, using the same data.
- Switch users over for that slice only, and watch it for a few weeks.
- Repeat until the old system has nothing left to do.
Your team gets improvements in weeks, not at the end of a long project. A bad slice gets rolled back alone. And you discover the hidden rules one area at a time, with the old code still there to check against.
It is not the right fit when you cannot intercept requests to the old system, or when the system is small enough to replace outright. A tiny tool with five screens is often better rebuilt in one go.
How should you think about the cost?
Do not compare "cost to rebuild" against "zero." Compare total cost over the same period, say three years, for each path:
- Refactor: the refactoring work, plus maintenance, plus features that still take longer than on a new system.
- Full rebuild: build cost, plus running the old system meanwhile, plus duplicate changes, migration, training and a buffer for surprises.
- Incremental replacement: similar build cost, spread over time, with less duplicate work and earlier payback as each slice ships.
Then add what spreadsheets usually miss: staff hours lost each week to workarounds, re-entry and waiting. Multiplied over three years, that is often the biggest figure on the page, and returning those hours to the business is usually the real reason to act.
Rebuild vs refactor decision checklist
Answer these honestly. Mostly "yes" in the first group points to refactoring. Mostly "yes" in the second points to rebuilding, ideally incrementally.
Leaning refactor:
- Does the software still match how your team works today?
- Is the language and framework still supported and patched?
- Are most problems concentrated in a few areas?
- Is the data model basically sound?
- Can a developer read the code and make a change in days, not weeks?
Leaning rebuild:
- Has the business model changed in ways the system cannot express?
- Is it running on unsupported or insecure technology?
- Is every change risky because nobody understands the side effects?
- Do you need integrations the architecture cannot support?
- Are yearly upkeep costs approaching what a replacement would cost over a few years?
Either way:
- Can you list the system's hidden rules and edge cases? If not, document them first.
- Can the old system run safely for several more months? Then incremental replacement is on the table.
Quick answers
Is it better to rebuild or refactor legacy software?
Most of the time, refactor or replace it in slices. A full rewrite only makes sense when the system's purpose or platform is fundamentally wrong, and even then an incremental approach is usually safer.
How do I know if my code is too far gone to refactor?
If nobody can make a change without breaking something unrelated, there are no tests, and the platform is unsupported, refactoring gets very expensive. That is the point where rebuilding, slice by slice, starts to win.
Can we rebuild without shutting down the old system?
Yes. With the strangler pattern, the old system keeps running while new pieces take over one area at a time. Users move gradually and you can roll back any single piece.
Should we change tech stacks in a rebuild?
Only for a clear reason, such as an unsupported platform or a hiring problem. Changing stack adds learning time and risk, so do not do it just because something newer exists.
Next step
If you are weighing a rebuild or a refactor, we can review your system, map the hidden rules and show you which path costs less over time, then stay on as a long-term partner for whichever you choose. Book a free call and we will send you a written recommendation within a few days.